The first version of an AI feature is usually judged on one question: does the answer look good? The second version gets judged on three more. How long does it take? What does each request cost? And what happens when the model is slow, wrong, or down?
Those questions decide whether a feature survives contact with real users. Here is how I approach them, independent of which model or framework you use.
Give the feature a budget
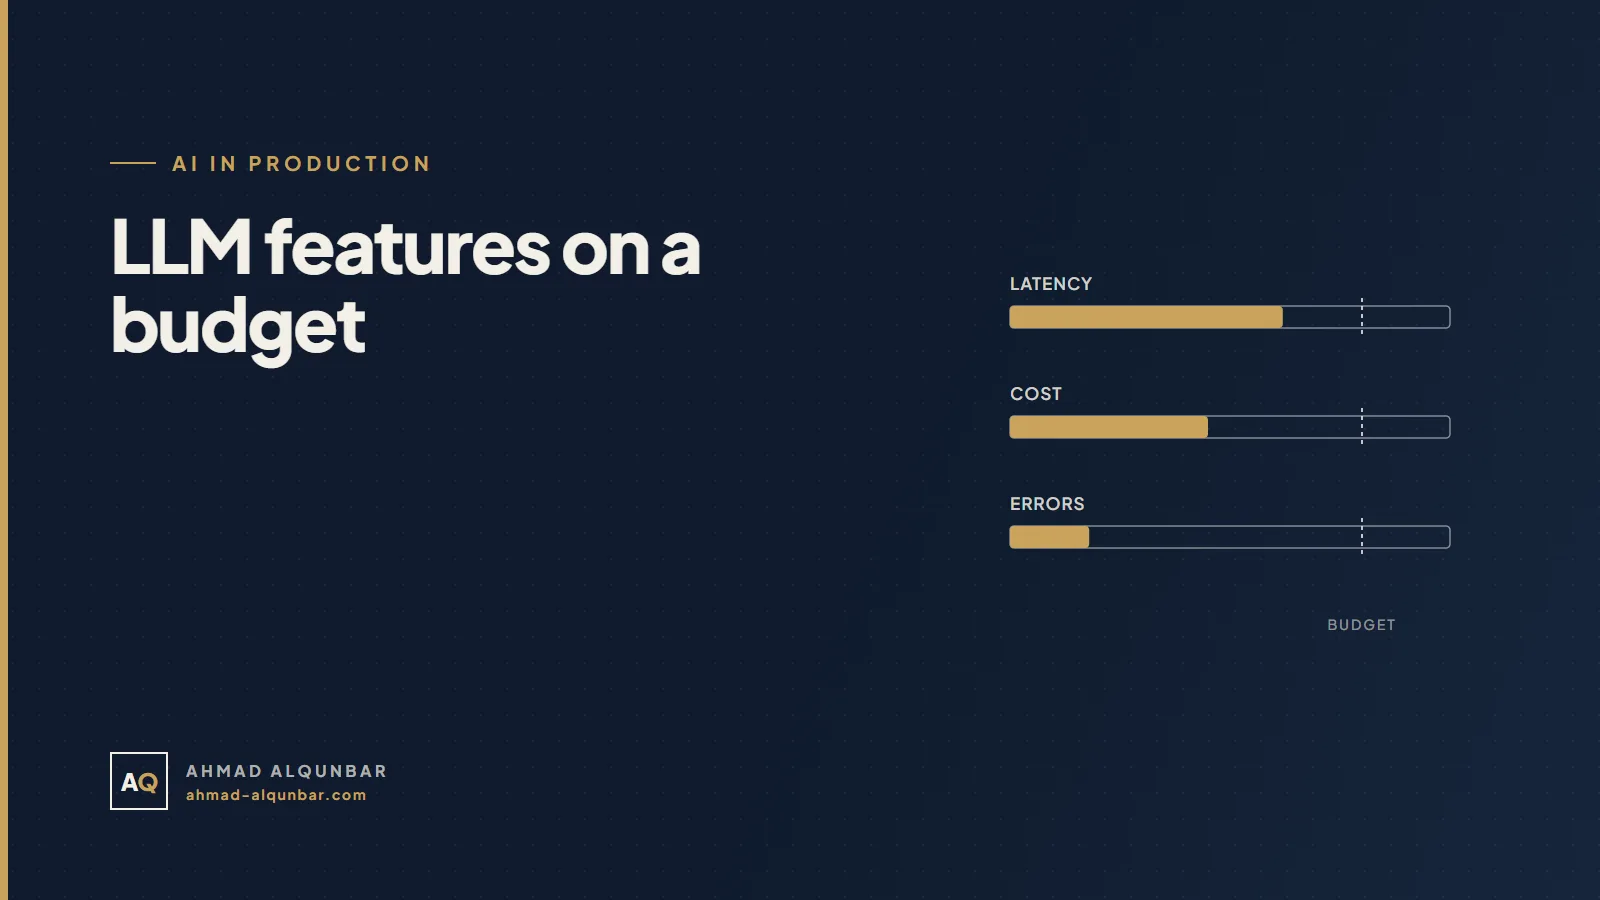
Before optimising anything, write down three numbers for the feature:
- Latency budget: for example, the first token within 1.5 seconds and a full answer within 8 seconds at the 95th percentile.
- Cost budget: a maximum cost per request, and a monthly ceiling per customer.
- Error budget: the share of requests allowed to fail or fall back before someone is paged.
Without numbers, "make it faster" and "make it cheaper" have no finish line. With them, every change below can be judged by whether it moves the right number.
Measure per feature, not per bill
The provider's invoice tells you what you spent in total. It doesn't tell you which feature spent it. Log every model call with the feature name, model, input and output tokens, latency, cache hit or miss, and outcome. Then you can answer the questions that matter: which feature costs the most per active user, which prompt grew from 2,000 to 9,000 tokens after the last release, and which tenant is responsible for half the spend.
Use the smallest model that passes the evaluation
Most products send every request to the largest model they have. Many requests don't need it. Classifying a support ticket, extracting fields from an invoice, or routing a question are tasks that smaller, faster, cheaper models handle well.
Route by task. Keep a small evaluation set for each task, around 50 to 200 real examples with expected outputs, and promote a cheaper model only when it passes the same evaluation. Without the evaluation set, "cheaper" quietly becomes "worse".
Spend tokens on purpose
Input tokens are usually the larger share of the cost, and they are the easiest to cut.
- Trim the prompt. Long system prompts accumulate rules nobody remembers adding. Review them like code.
- Retrieve less, retrieve better. Sending twenty retrieved chunks "to be safe" costs more and often answers worse than five good ones. Tune how many chunks you send against your evaluation set.
- Summarise history. A chat that resends the full conversation every turn grows in cost with every message. Keep recent turns verbatim and summarise the rest.
- Cap the output. Set a maximum output length that matches the feature. A field extractor doesn't need room for an essay.
Cache what repeats
Exact caching is safe and effective: the same input with the same model and the same prompt version returns the stored output. Include the prompt version in the cache key so a prompt change invalidates old answers.
Similarity-based caching, which reuses answers for questions that are merely similar, is riskier. "Cancel my order" and "don't cancel my order" can look alike to an embedding. Use it only where a slightly wrong answer is harmless, and measure how often it is wrong.
Embeddings for documents that haven't changed should never be computed twice. Store them with a hash of the source text and skip unchanged documents on re-index.
Make it feel fast
Perceived latency matters as much as real latency. Stream answers so the first words appear while the rest are generated. Run independent steps in parallel: retrieval, permission checks, and loading the user's context don't need to wait for each other. Move work that doesn't need an immediate answer, such as summarising a long document, to a background job and notify the user when it's done.
Plan for the bad day
Model providers have incidents, rate limits, and slow hours. Treat the model as an unreliable dependency:
- Timeouts on every call, set from the latency budget rather than library defaults.
- Retries with exponential backoff and jitter, only for errors that are worth retrying, such as rate limits and transient server errors.
- A circuit breaker that stops calling a failing provider for a short time instead of piling up requests.
- A fallback: a second model or provider for the same task, a cached answer, or a non-AI path such as a plain search result.
- An honest message when nothing works, with the user's input saved so they don't have to retype it.
Put limits where customers can see them
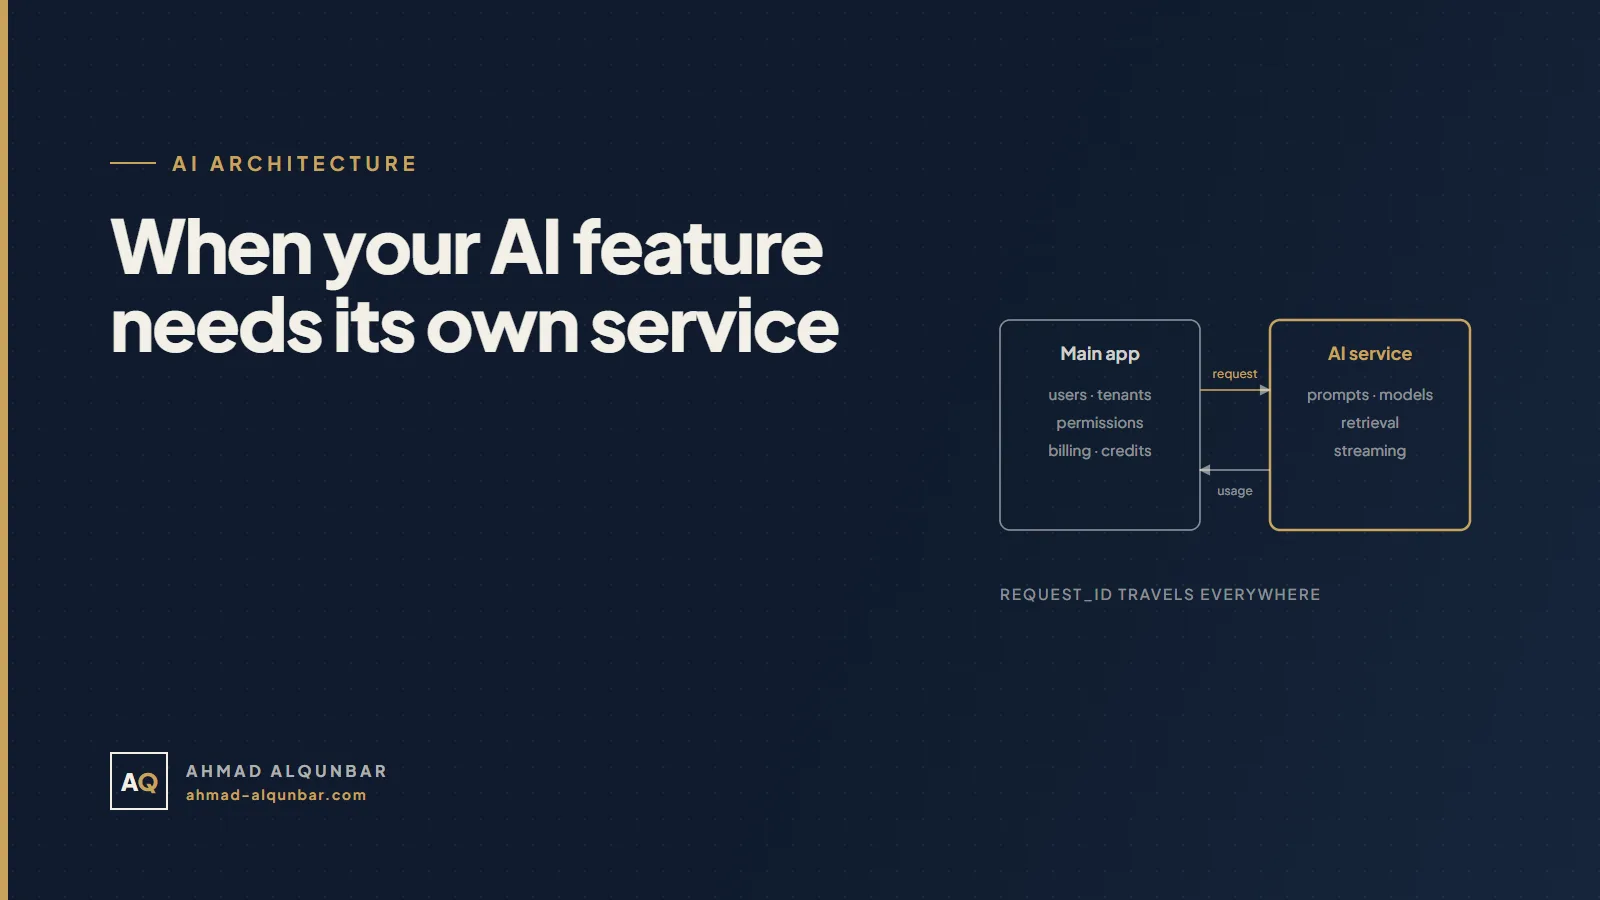
If customers pay per use or have a plan, enforce limits before the call. Check the remaining credits or quota, reserve an estimate, run the request, then settle the actual cost in a usage ledger. Show customers their usage. A clear meter prevents more support tickets than any apology email.
The checklist
- Latency, cost, and error budgets written down per feature.
- Every call logged with feature, model, tokens, latency, and outcome.
- The smallest model that passes the evaluation set, per task.
- Prompts reviewed, retrieval tuned, history summarised, outputs capped.
- Exact caching keyed by prompt version; no recomputed embeddings.
- Streaming, parallel steps, and background jobs for perceived speed.
- Timeouts, retries with jitter, a circuit breaker, and a fallback.
- Credits checked before the call and settled in a ledger after it.
None of these makes a demo more impressive. All of them make the feature cheaper, faster, and still standing on the day the provider has a bad afternoon.