"The app is slow" is not a problem you can fix. It is a feeling, and every developer on the team will guess a different cause for it. The guesses are usually wrong, and the fixes that follow them add complexity without making anything faster.
What works is a short, boring workflow: define the slow thing, measure it, find where the time actually goes, remove work before adding cleverness, and prove the result. It applies whatever language or framework you use.
1. Name the slow thing
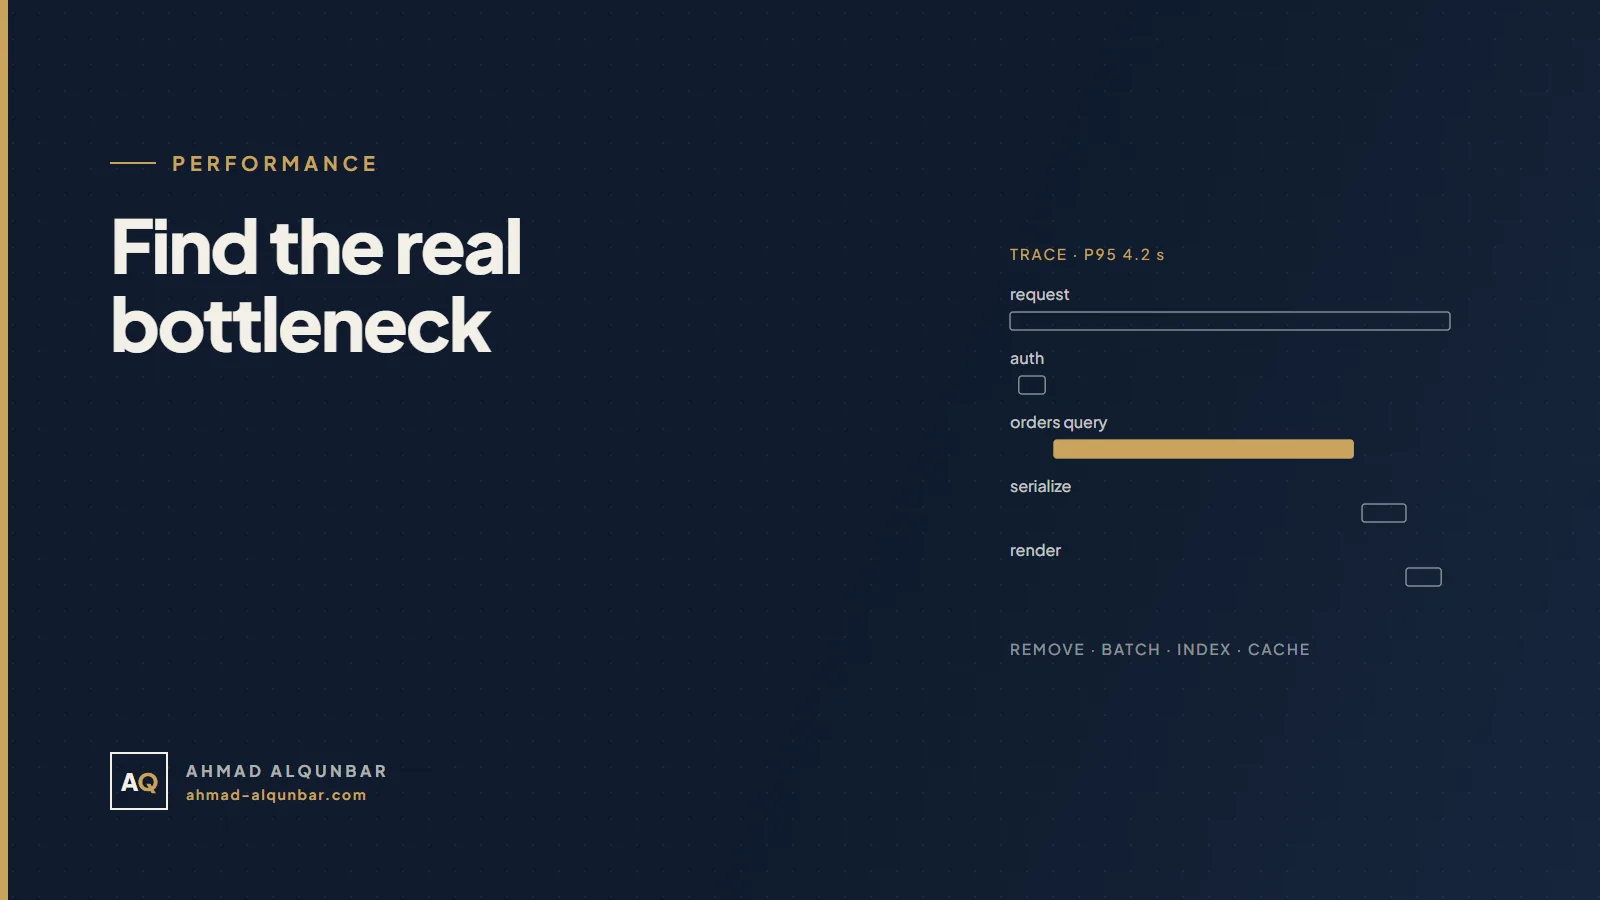
Pick one specific user action and one number. "The orders list for a tenant with 50,000 orders takes 4.2 seconds at the 95th percentile" is a problem you can fix. "The dashboard feels heavy" is not.
Use percentiles, not averages. An average of 300 ms can hide the fact that one request in twenty takes six seconds, and those are the requests users remember.
2. Reproduce it with real data
Most performance bugs don't exist on a laptop with 50 rows. Reproduce with production-shaped data: the same number of records, the same distribution, and the same large tenants. An anonymised copy of production, or a generated dataset that matches its size, saves days of guessing.
3. Find where the time goes
Look before you change anything. Tracing or an APM tool will show you, for one slow request, how long each database query, external call, and block of code took. Without one, query logs and timing around the suspicious parts get you most of the way.
In business applications the time usually goes to a short list of suspects:
- N+1 queries: one query for a list, then one more for each row to load a relation. Fifty rows become fifty-one queries.
- Missing or unused indexes: a query that scans a whole table to find a few rows. Ask the database how it runs the query with
EXPLAINinstead of guessing. - Over-fetching: loading every column of every row when the page shows ten rows and four fields.
- External calls inside the request: a payment provider, a delivery API, or a model call that the user waits for even though they don't need its result to see the page.
- Serialisation: building large nested responses the client mostly ignores.
- Lock contention: many requests waiting on the same row or table.
4. Fix in this order: remove, batch, index, cache
The order matters, because the earlier fixes are simpler and have fewer side effects.
Remove work. The fastest query is the one you don't run. Drop unused relations from the response, stop recalculating totals that never change, and paginate lists that render thousands of rows nobody scrolls to.
Batch work. Replace N+1 with eager loading or a single query with a join. Send one bulk insert instead of a thousand single inserts. Fetch the twenty products you need in one call, not twenty.
Index for the query you actually run. A composite index on (tenant_id, status, created_at) serves a query that filters by tenant and status and sorts by date. The same columns in a different order may not. Check the plan again after adding the index, and remove indexes nothing uses, because every index slows down writes.
Cache last. Caching is powerful and dangerous: every cache is a second copy of the truth that can be stale. Cache things that are expensive to compute and rarely change, key them carefully (including the tenant in multi-tenant apps), and decide up front how each entry is invalidated.
5. Move work out of the request
If the user doesn't need the result to see the next screen, don't make them wait for it. Sending emails, generating PDFs, syncing with third parties, and recalculating reports belong in background jobs.
For dashboards, precompute. A summary table updated as orders change, or refreshed every few minutes, is far cheaper than aggregating a million rows on every page load. Users rarely need to-the-second totals on a chart.
6. Paginate properly
Offset pagination (LIMIT 50 OFFSET 100000) gets slower the deeper you go, because the database still walks every skipped row. For long lists and infinite scroll, use keyset pagination: "the next 50 orders created before this timestamp and ID". It stays fast on page one and page two thousand.
7. Prove it, and keep it proven
Measure the same action, with the same data, after the change, and write both numbers in the pull request. "4.2 s to 380 ms at p95" is a result. "Optimised the orders page" is a claim.
Then protect the result. Add a test that asserts the number of queries an endpoint runs, so a new N+1 fails the build. Set alerts on the p95 latency of your most important routes. Performance is not fixed once; it is defended release by release.
The checklist
- One user action, one percentile number.
- Production-shaped data to reproduce it.
- Tracing or query logs before any change.
- Remove, then batch, then index, then cache.
- Slow, non-essential work in background jobs; dashboards precomputed.
- Keyset pagination for deep lists.
- Before-and-after numbers, query-count tests, and latency alerts.
None of it is glamorous, and that is the point. Most slow applications don't need a rewrite. They need someone to look at where the time actually goes.